A museum of ZFS, read in its source

Uberblok

Uberblok explains how ZFS keeps data safe through crashes, failing disks and interrupted writes. Most rooms take one idea, show it in a figure you can operate, and quotes the OpenZFS code that implements it.

The figures and excerpts follow OpenZFS zfs-2.4.4, frozen at commit 71a9f9578616. Every excerpt is checked against that commit, and none is written from memory.

All rooms · Why this museum?

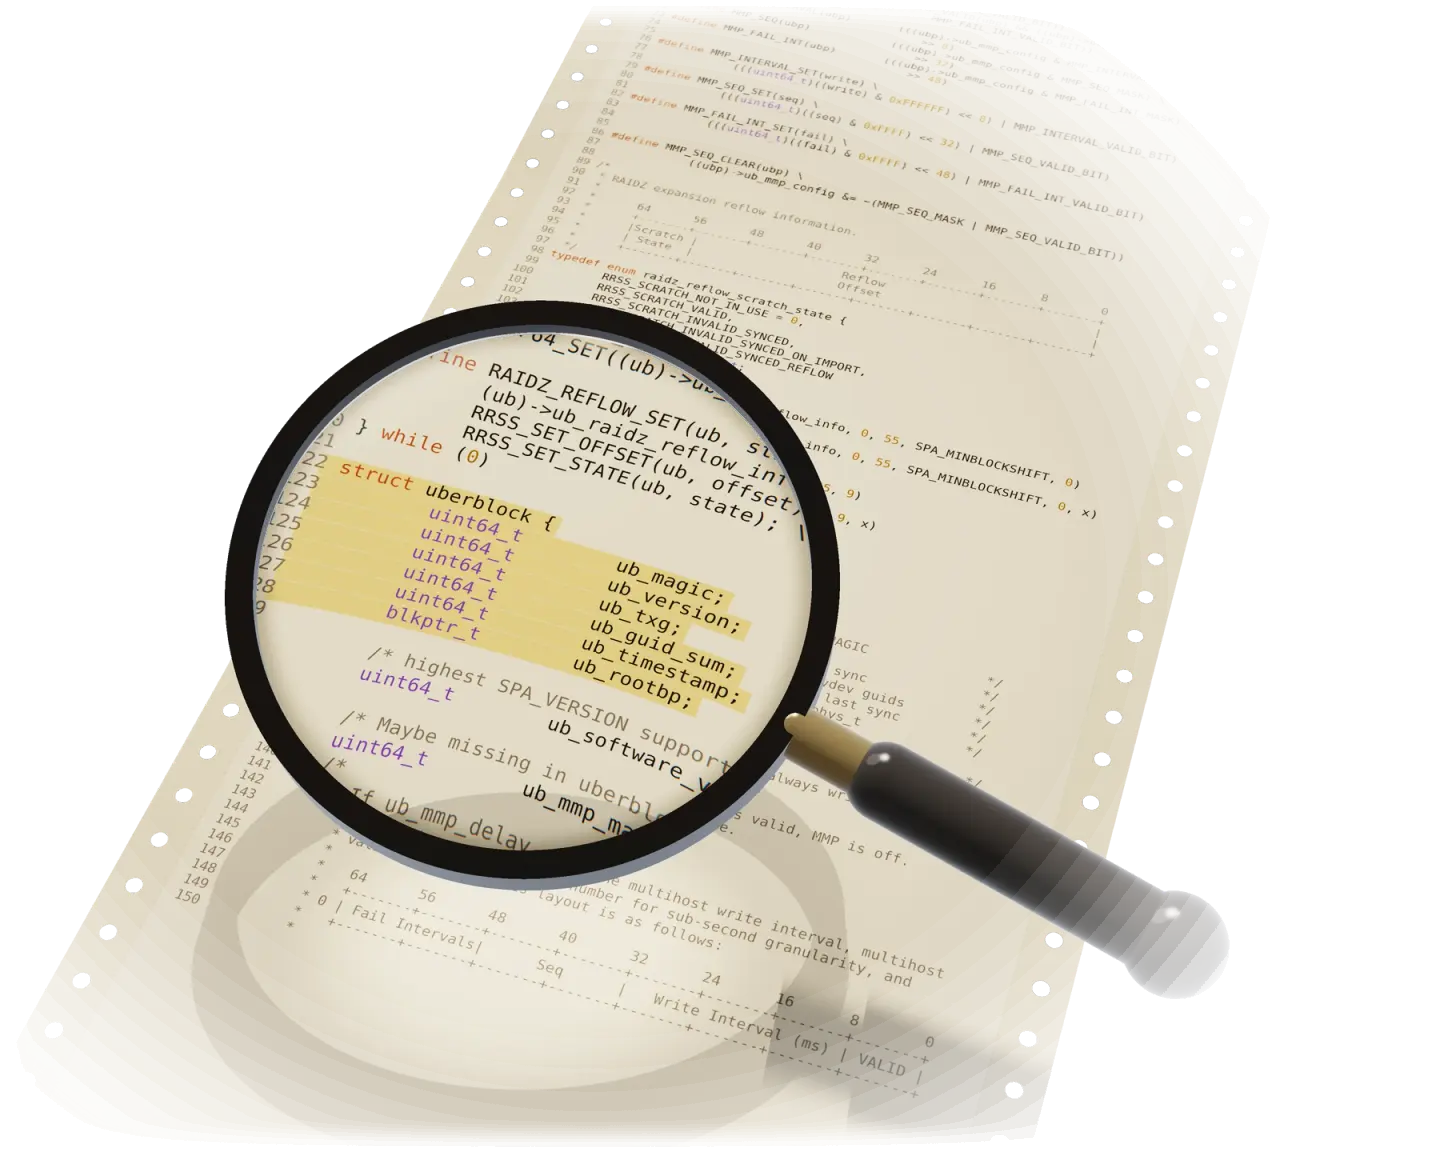
Rendering of a strip of fan-fold listing paper printed with the OpenZFS file include/sys/uberblock_impl.h, its far end fading away. A round reading glass with a black rim and a black handle, held above it, enlarges the highlighted declaration of struct uberblock: uint64_t ub_magic, ub_version, ub_txg, ub_guid_sum, ub_timestamp and blkptr_t ub_rootbp stand out larger than the lines around them. The glass casts a soft shadow, with a bright spot, on the paper below.

Fig. 1. The Hall’s object under the glass: struct uberblock, lines 122–128 of include/sys/uberblock_impl.h at zfs-2.4.4, printed with lines 36–150 of its file.

  1. struct uberblock: the record that names the whole pool
  2. ub_txg: the transaction group of the last sync
  3. ub_rootbp: the block pointer to the root of the tree, the MOS
  4. The listing: lines 36 to 150 of the file, numbered as in the source

The uberblock

How does ZFS find its data after a crash?

A pool holds millions of blocks spread over several disks. After a crash, ZFS has to find the last consistent state of the pool without reading all of them. It starts from one small record on each disk, the uberblock. ZFS writes changes in batches called transaction groups (txg), one every few seconds. The uberblock holds the number of the last txg and a pointer to the top of the pool’s tree of blocks. Every other block can be reached from that pointer.

ZFS never writes a new uberblock over the current one. Each disk keeps a ring of slots for uberblocks, and each txg writes its uberblock to the next slot. The previous uberblock stays intact in its own slot, so a power failure during the write still leaves a good one on disk.

When the pool is imported, ZFS reads every slot, sets aside the ones that fail their check, and uses the valid uberblock with the highest txg.

The figure shows one ring. Press Next txg to commit one txg: the new uberblock takes the slot after the previous one, and the previous one stays in its slot. When animations are on, the ring also commits a txg every 1.3 seconds by itself, and Next txg stops it. Change the sector size of the disks. A slot takes one sector, and never less than 1 KiB, so the same 128 KiB ring holds 128 slots on disks with 512-byte sectors and 32 on disks with 4 KiB sectors.

txg 4211
ub_magic
0x00bab10c
ub_txg
4211
ub_rootbp
→ MOS

Ring of 32 slots of 4 KiB (ashift 12). The uberblock of txg 4211 is the newest: slot 19, because 4211 mod 32 = 19. The uberblock of txg 4210 is still intact in slot 18.

Every uberblock starts with the same magic number, 0x00bab10c, read aloud as “oo-ba-bloc”.

In the code

The figure follows three places in the OpenZFS source. Open a Source note to see the lines, taken from release zfs-2.4.4.

The record

struct uberblock starts with a magic number and the on-disk version. It also holds the txg, the time of the sync and ub_rootbp, the block pointer to the pool’s own metadata, from which the rest of the tree hangs.

Source struct uberblock, uberblock_impl.h
uberblock Excerpt of include/sys/uberblock_impl.h, lines 122–128, OpenZFS zfs-2.4.4. View on GitHub
struct uberblock {
	uint64_t	ub_magic;	/* UBERBLOCK_MAGIC		*/
	uint64_t	ub_version;	/* SPA_VERSION			*/
	uint64_t	ub_txg;		/* txg of last sync		*/
	uint64_t	ub_guid_sum;	/* sum of all vdev guids	*/
	uint64_t	ub_timestamp;	/* UTC time of last sync	*/
	blkptr_t	ub_rootbp;	/* MOS objset_phys_t		*/
  1. L123 UBERBLOCK_MAGIC is 0x00bab10c. A slot without it is not an uberblock.
  2. L125 The txg of the last sync. On import, the highest valid one wins.
  3. L128 The block pointer to the MOS, the pool’s own metadata. Every other block of the pool is reached from here.

The slot of a txg

vdev_uberblock_sync picks the slot: the txg modulo the number of slots. The txg grows by one at each sync, so the uberblocks go round the ring and the newest one never lands on the one before it.

Source vdev_uberblock_sync, vdev_label.c
vdev_uberblock_sync Excerpt of module/zfs/vdev_label.c, lines 1782–1784, OpenZFS zfs-2.4.4. View on GitHub
	int m = spa_multihost(vd->vdev_spa) ? MMP_BLOCKS_PER_LABEL : 0;
	int n = (ub->ub_txg - (RRSS_GET_STATE(ub) == RRSS_SCRATCH_VALID)) %
	    (VDEV_UBERBLOCK_COUNT(vd) - m);
  1. L1782 With multihost=on, the last slot is kept for MMP and the ring turns on one slot fewer.
  2. L1783–L1784 VDEV_UBERBLOCK_COUNT is the 128 KiB ring divided by the slot size: one sector, at least 1 KiB and at most 8 KiB. The RRSS_SCRATCH_VALID term only matters during a RAID-Z expansion. The same slot is then written in each of the four labels.

The choice on import

On import, vdev_uberblock_load_done runs once for every slot read. It ignores a slot whose read failed or whose magic number is wrong, and keeps the uberblock that compares highest.

Source vdev_uberblock_load_done, vdev_label.c
vdev_uberblock_load_done Excerpt of module/zfs/vdev_label.c, lines 1547–1551, OpenZFS zfs-2.4.4. View on GitHub
	if (zio->io_error == 0 && uberblock_verify(ub) == 0) {
		mutex_enter(&rio->io_lock);
		if (vdev_uberblock_compare(ub, &cbp->ubl_latest) > 0) {
			cbp->ubl_latest = *ub;
		}
  1. L1547 Every slot of every label of every readable disk is read. A slot carries its own checksum, so a damaged one fails the read here.
  2. L1549–L1550 vdev_uberblock_compare compares the txg first, then the timestamp.

What the figure leaves out

The figure shows one ring. A disk carries four labels, two at its start and two at its end, each with its own ring, and every txg writes the same slot in all four. The ring is often said to hold 128 uberblocks. That is true only for 512-byte sectors: it holds 128 KiB, so 64 slots at ashift 11, 32 at ashift 12 and 16 from ashift 13. With multihost=on one slot is kept for MMP. The txg numbers are made up.

All rooms

Most rooms explain one part of ZFS with a figure and the code behind it. After the Hall and the history of ZFS, the list follows the data, from the root of the pool to the features built on it. Each room can be read on its own. The last one, the engine room, says how this site was made.

  1. Hall: the uberblock The one record that names the whole pool, and the ring that keeps it.
  2. History wing From the first lines of code to OpenZFS, every fact sourced.
  3. The tree and the uberblock Block pointers all the way down, and the write that makes a new tree the current one.
  4. Copy-on-write, checksums and self-healing Why a pool stays consistent without fsck, and how it catches a disk that lies.
  5. Transaction groups Open, quiescing, syncing: how thousands of writes become one commit.
  6. The vdevs Mirror, raidz, draid, log, cache, special: the tree of devices under a pool.
  7. RAID-Z Variable-width stripes, and why there is no write hole.
  8. Snapshots and clones Birth times and deadlists: which snapshot owns this block?
  9. The ARC A cache that learns from what it forgot.
  10. Metaslabs and space maps Finding free space fast, with an append-only log of allocations.
  11. ZIL and SLOG The path of a synchronous write.
  12. send / receive A dataset as a stream, and the increment between two snapshots.
  13. Compression, dedup, encryption Three transforms in the write pipeline, and the honest cost of dedup.
  14. Engine room How this museum was built, and from which commit.

Dedication

Why this museum?

Keeping data safe is critical work, and seldom seen. A file system is handed everything people keep, and it has to stay right through crashes, failing disks and writes cut short. One of the principles ZFS was designed on, in Bill Moore’s words: never, ever trust the underlying hardware.1

This museum pays homage to that piece of engineering, and to the people who built it. Jeff Bonwick led the development of ZFS, with Bill Moore as co-lead;1 Matt Ahrens was one of its two original authors.2 The work began in 2001 with two engineers at Sun Microsystems3 and was integrated into Solaris on 31 October 2005,4 a step Bonwick summed up as 584 files, 92,000 lines of change, 56 patents, 5 years.4 On 17 November he wrote: I’m incredibly proud of the ZFS team, and deeply grateful: no one person can do something on this scale.5

It pays homage, too, to the engineering at Sun in those years, where engineers published how their systems worked: the slab allocator, presented by Jeff Bonwick at USENIX in 1994;6 DTrace, by Bryan Cantrill, Michael Shapiro and Adam Leventhal, in 2004;7 and the source of ZFS itself, released under the CDDL as part of OpenSolaris.3

And to those who carry it on: OpenZFS, announced in 20132 and founded by members of the Linux, FreeBSD, Mac OS X and illumos communities.2 The release this museum reads lists more than 700 people in its AUTHORS file.
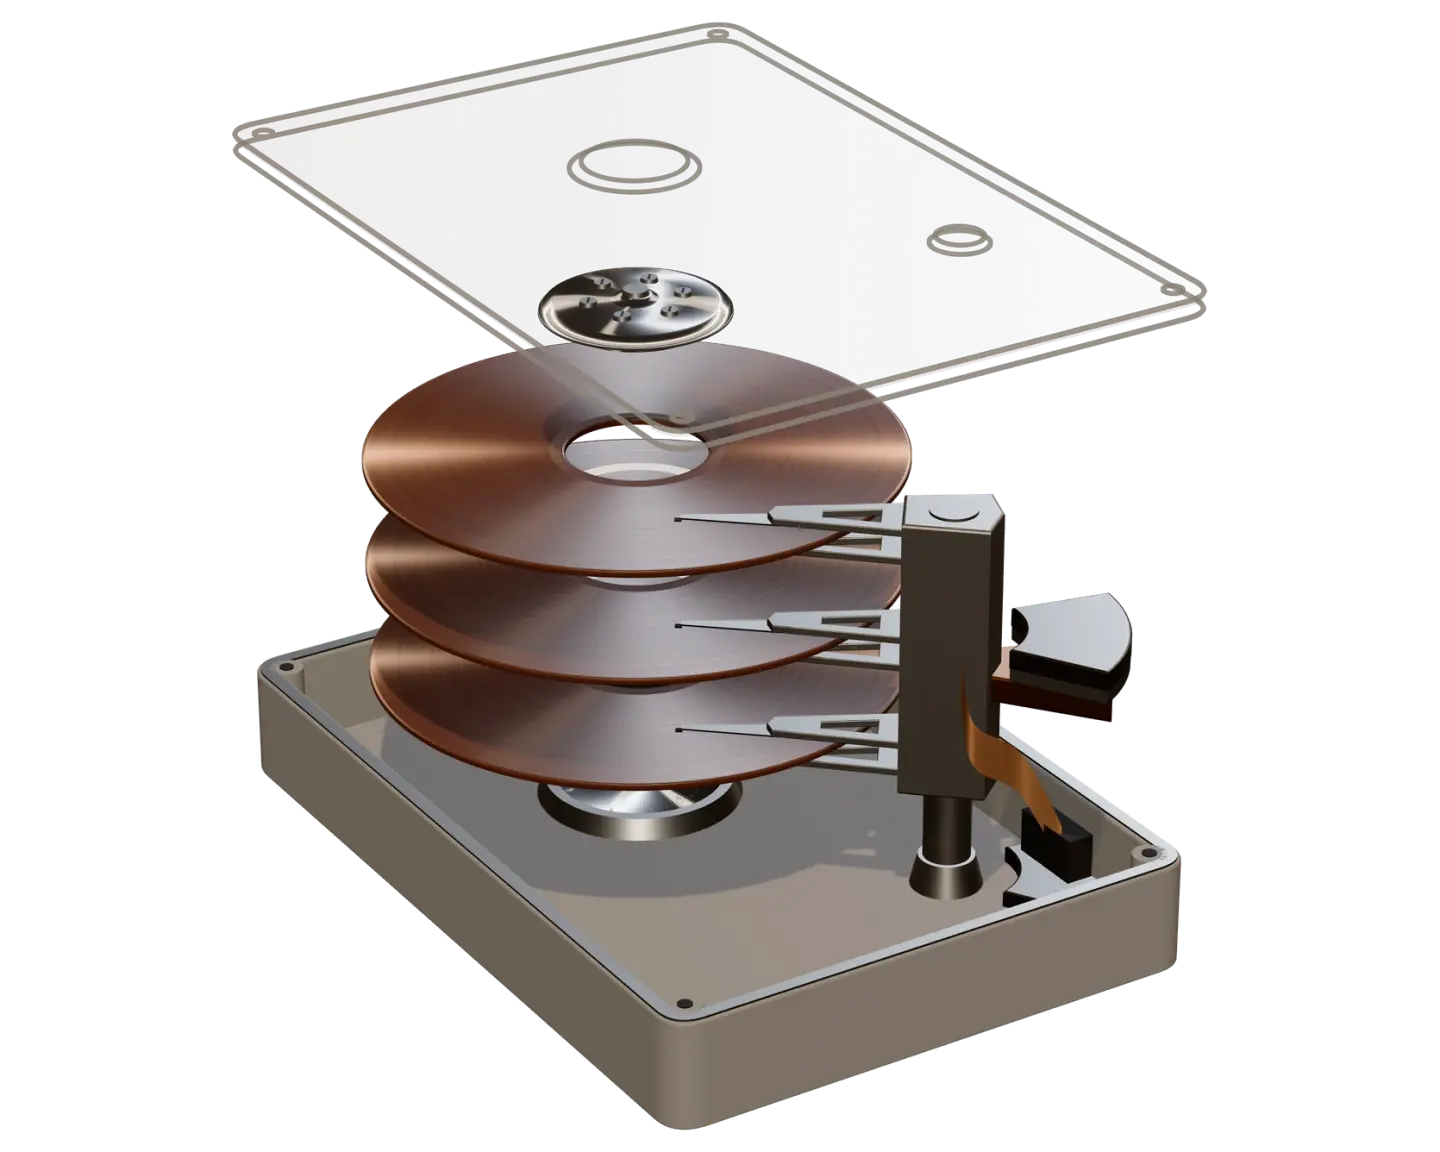
Rendering of a hard disk taken apart along its spindle: the base, the motor, three glossy brown platters, the clamp and, highest, the cover drawn in outline; the arms of the head stack reach over the platters.

Fig. 2. The underlying hardware: a 3.5-inch hard disk, exploded along its spindle.

  1. Top cover
  2. Disc clamp
  3. Platters
  4. Head stack: arms and heads
  5. Voice coil and its magnet
  6. Spindle motor
  7. Base casting

Sources

  1. 1 “A Conversation with Jeff Bonwick and Bill Moore”, ACM Queue 5(6), November 2007 (archived 2011-07-16)
  2. 2 OpenZFS launch announcement, open-zfs.org (archived 2013-09-20)
  3. 3 openzfs.org wiki, “History” (archived 2020-05-14)
  4. 4 Jeff Bonwick, “ZFS: The Last Word in Filesystems”, blog post of 31 October 2005 (archived 2007-02-07)
  5. 5 Jeff Bonwick, blog, posts of November 2005, “Thank You” of 17 November 2005 (archived 2006-12-19)
  6. 6 USENIX, abstract of “The Slab Allocator: An Object-Caching Kernel Memory Allocator”, Summer 1994 Technical Conference (archived 2001-02-21)
  7. 7 USENIX, abstract of “Dynamic Instrumentation of Production Systems”, 2004 Annual Technical Conference (archived 2006-01-07)